zai-org/GLM-5.3 — model analysis
Summary
- Size: The model consists of about 753 billion numbers (parameters). Its saved files total about 756GB.
- Structure: A mixture-of-experts (MoE) model that, for each input, selects only 8 of its 256 experts. Of about 753 billion parameters in total, about 41.3 billion are used per computation step. About 96% of the parameters are assigned to the experts, about 2% to the part that reads context (attention), and about 1% to the multi-token prediction part (MTP).
- Japanese text: In Japanese, one token holds about 1.3 characters. In English, one token holds about 4.3 characters. For the same number of characters, Japanese needs about 3.2 times as many tokens as English. Of its 154,856 vocabulary entries, 29,521 contain kana or kanji.
- Context length: The limit written in the config (max_position_embeddings) is 1,048,576 tokens, roughly 1,400,000 Japanese characters or 4,500,000 English characters at the same ratio as the fixed texts above.
- Skew in values: Values inside the model flow in groups of 6,144. Positions 3203 and 4386 were among the positions where outliers (extremely large values) appear most often, in all 78 layers. Positions 3203 and 4386 also appeared in the tally of positions where normalization-layer weights take extreme values (3203: 93, 4386: 138 of 355 normalization layers). This kind of skew is generally considered a cause of accuracy loss when a model is compressed (quantized).
One line: MoE (8 of 256 experts active) · glm_moe_dsa · 78 layers · 753.33B params · 41.25B active · MLA · context 1,048,576 · vocab 154,880
Basic information
- Model: zai-org/GLM-5.3 (revision
aca966e4e027, config.json) - License: glm-5.3
- Declared base_model: none
- Storage dtypes: F8_E4M3 751.23B, BF16 2.10B, F32 45.87M
Architecture (stage 0)
Parameters by part
Counted from the tensor shapes in the safetensors headers (measured).
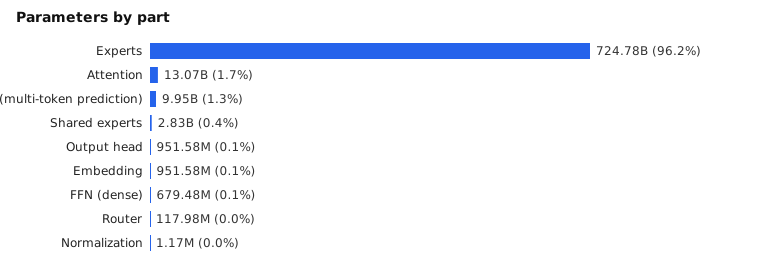
| Part | Parameters | Share |
|---|---|---|
| Experts | 724,775,731,200 | 96.21% |
| Attention | 13,068,337,152 | 1.73% |
| MTP (multi-token prediction) | 9,952,920,576 | 1.32% |
| Shared experts | 2,831,155,200 | 0.38% |
| Output head | 951,582,720 | 0.13% |
| Embedding | 951,582,720 | 0.13% |
| FFN (dense) | 679,477,248 | 0.09% |
| Router | 117,984,000 | 0.02% |
| Normalization | 1,169,664 | 0.00% |
Structure
Values from config.json.
| Item | Value |
|---|---|
| model_type / architectures | glm_moe_dsa / GlmMoeDsaForCausalLM |
| Layers | 78 |
| Hidden size | 6,144 |
| FFN intermediate size | 12,288 |
| Attention type | MLA |
| Heads / KV heads / head dim | 64 / 64 / 192 |
| MLA settings | q_lora_rank=2048, kv_lora_rank=512, qk_rope_head_dim=64, qk_nope_head_dim=192, v_head_dim=256 |
| Sliding window | — (use_sliding_window=—) |
| Layer types (layer_types) | — |
| RoPE θ | 8,000,000 |
| RoPE scaling | {'rope_theta': 8000000, 'rope_type': 'default'} |
| Partial rotary (partial_rotary_factor) | — |
| Context length (max_position_embeddings) | 1,048,576 |
| Tied input/output embeddings | No |
| Activation | silu |
| Normalization ε | 1.000e-05 |
MoE configuration
Expert counts come from both config and tensor names (MTP layers excluded). Active parameters = total − MTP − expert part + expert part × active ÷ experts (computed).
| Item | Value |
|---|---|
| Experts (config) | 256 |
| Experts counted from tensor names (count: layers) | 256:75 layers |
| Active experts per token | 8 |
| Shared experts | 1 |
| MoE layers | 75 |
| Leading dense layers (first_k_dense_replace) | 3 |
| Expert parameters | 724.78B |
| Active parameters | 41.25B |
| MTP parameters (excluded from active) | 9.95B |
config vs. actual tensors
Values in config.json side by side with the actual tensor shapes (measured).
| Item | config | Actual | Match | Source of actual |
|---|---|---|---|---|
| vocab_size | 154,880 | 154,880 | Yes | model.embed_tokens.weight |
| hidden_size | 6,144 | 6,144 | Yes | model.embed_tokens.weight |
| num_hidden_layers | 78 | 78 | Yes | largest layer index + 1 (excluding MTP layers) |
| intermediate_size | 12,288 | 12,288 | Yes | model.layers.0.mlp.gate_proj.weight |
| tie_word_embeddings (no output-head tensor) | No | No | Yes | tensor list |
| num_experts | 256 | 256 | Yes | tensor names |
Tokenizer
Results of tokenizing the fixed Japanese and English texts (see conditions) without special tokens (measured). "Tokens splitting a character" is the share of tokens that decode to a broken character (U+FFFD) on their own.
| Text | Characters | Tokens | Chars/token | Bytes/token | Tokens splitting a character | Round-trips exactly |
|---|---|---|---|---|---|---|
| Japanese | 449 | 336 | 1.336 | 4.003 | 6.0% | Yes |
| English | 1,201 | 282 | 4.259 | 4.358 | 0.0% | Yes |
Of 154,856 vocabulary entries, 29,521 (19.06%) contain at least one kana or kanji character and 24,483 contain two or more (loaded with tokenizers).
Special tokens and chat format
18 special tokens. BOS: None, EOS: <|endoftext|>. Chat template: present (10734 characters, sha256 prefix 3740abcea51c).
Thinking tags: Yes, tool calls: Yes, FIM: No, image tokens: No (found by searching special-token names and the template text).
List of special tokens
<|endoftext|>, [MASK], [gMASK], [sMASK], <sop>, <eop>, <|system|>, <|user|>, <|assistant|>, <|observation|>, <|begin_of_image|>, <|end_of_image|>, <|begin_of_video|>, <|end_of_video|>, <|begin_of_audio|>, <|end_of_audio|>, <|begin_of_transcription|>, <|end_of_transcription|>
Weights (stage 1)
Analyzed 59,585 of 118,629 tensors (compute time 11.8 min). Each tensor was converted to fp32 for computation. Tensors excluded from analysis: FP8 scale (not a weight) (59044). The 791 tensors of the MTP (multi-token prediction) part (layer 78) were analyzed but kept out of the per-layer trends, outlier channels, normalization-layer dimensions, embedding rows, expert similarity and extremes below, so that only the main layers are counted. Weights stored in FP8 (59,044) were restored to fp32 by multiplying by their 128×128 block scales before computation.
Trends across layers
RMS is the root mean square of the elements. max|w| ÷ RMS is how many times larger the largest element is than a typical one. Excess kurtosis measures tail heaviness and is 0 for a normal distribution (all measured).
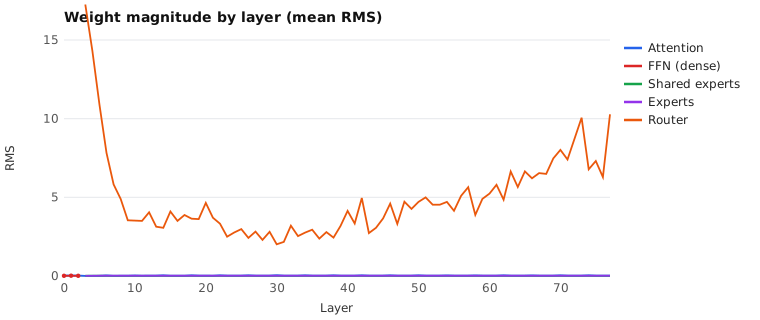
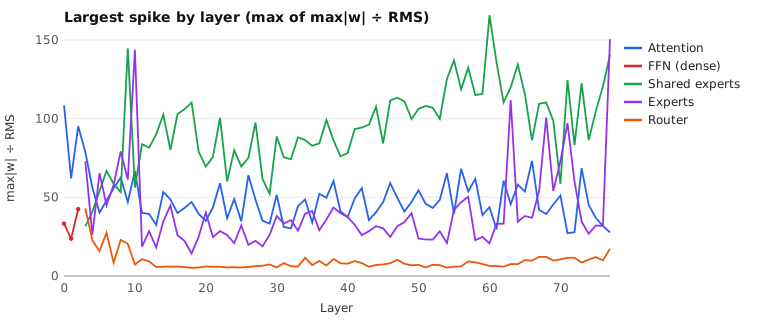
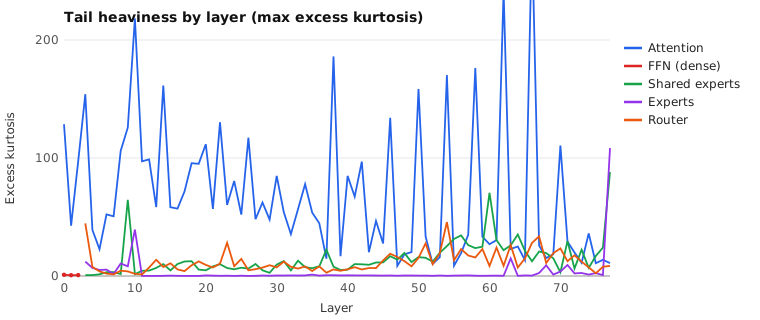
Matrices with the largest values: max|w| ÷ RMS 165.785 (model.layers.60.mlp.shared_experts.gate_proj.weight), excess kurtosis 291.449 (model.layers.66.self_attn.indexer.weights_proj.weight), outlier share 0.781% (model.layers.23.mlp.gate.e_score_correction_bias).
Outliers and outlier channels
An outlier is an element exceeding 6 times the standard deviation of its matrix. For each matrix that takes the hidden dimension as input, the columns with the most outliers (top 16) were collected, and the number of layers in which each column appeared was counted (measured).
| Hidden-dimension column | Layers it appeared in (of 78) |
|---|---|
| 3203 | 78 |
| 4386 | 78 |
| 2232 | 70 |
| 4801 | 70 |
| 506 | 66 |
| 2588 | 61 |
| 3257 | 54 |
| 2305 | 53 |
| 2674 | 52 |
| 447 | 50 |
Normalization-layer weights
For each of the 355 normalization layers, the dimensions farthest from the median (top 16) were collected, and the number of normalization layers in which each dimension appeared was counted (measured).
| Dimension | Normalization layers it appeared in |
|---|---|
| 4386 | 138 |
| 3203 | 93 |
| 4801 | 88 |
| 2232 | 78 |
| 506 | 61 |
| 1806 | 57 |
| 3015 | 55 |
| 2674 | 53 |
| 2906 | 48 |
| 5722 | 48 |
Dimensions shared with the top 10 outlier channels above: 506, 2232, 2674, 3203, 4386, 4801.
Effective rank
Stable rank = (Frobenius norm)² ÷ (largest singular value)², divided by the matrix's shorter side to scale it to 0–1. The largest singular value is approximated by power iteration (30 steps) (estimated).
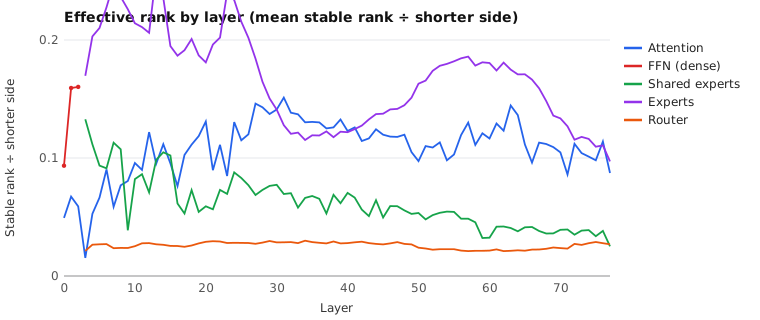
Stable rank ÷ shorter side by part:
| Part | Matrices | Min | Median | Max | Matrix with the minimum |
|---|---|---|---|---|---|
| Experts | 57600 | 0.0086 | 0.1642 | 0.4243 | model.layers.66.mlp.experts.161.gate_proj.weight |
| MTP (multi-token prediction) | 781 | 0.0108 | 0.0541 | 0.3518 | model.layers.78.mlp.experts.200.down_proj.weight |
| Attention | 453 | 0.0064 | 0.0598 | 0.4419 | model.layers.10.self_attn.indexer.wq_b.weight |
| Shared experts | 225 | 0.0202 | 0.054 | 0.247 | model.layers.77.mlp.shared_experts.up_proj.weight |
| Router | 75 | 0.0211 | 0.0269 | 0.0299 | model.layers.62.mlp.gate.weight |
| FFN (dense) | 9 | 0.0348 | 0.1236 | 0.2698 | model.layers.0.mlp.gate_proj.weight |
| Output head | 1 | 0.0031 | 0.0031 | 0.0031 | lm_head.weight |
| Embedding | 1 | 0.0216 | 0.0216 | 0.0216 | model.embed_tokens.weight |
Embedding rows
Distribution of the length (norm) of each vocabulary entry's embedding row, and the rows with the smallest norms (bottom 0.1%) (measured).
lm_head.weight (154,880 rows)
| Min | Bottom 0.1% | Bottom 1% | Median | Top 1% | Max |
|---|---|---|---|---|---|
| 0.4223 | 0.426 | 0.7756 | 1.5125 | 1.9259 | 5.0758 |
Rows with small norms (155 rows in the bottom 0.1%, the 20 smallest): 154289:'\u17fd'(0.4223), 154160:'\u0ffb'(0.4227), 154136:'\u0fe3'(0.4237), 154157:'\u0ff8'(0.424), 151330:'�'(0.4242), 154287:'\u17fb'(0.4246), 78632:' ForCanBeConvertedToF'(0.4248), 35118:'�'(0.4249), 61976:'�'(0.425), 24755:'�'(0.4251), 149816:'ással'(0.4252), 154131:'\u0fde'(0.4252), 91117:'�'(0.4253), 151336:'�'(0.4253), 149537:'ürlü'(0.4253), 148604:'астроф'(0.4254), 151338:'�'(0.4254), 83279:'$PostalCodesNL'(0.4255), 44002:'�'(0.4255), 151337:'�'(0.4256)
model.embed_tokens.weight (154,880 rows)
| Min | Bottom 0.1% | Bottom 1% | Median | Top 1% | Max |
|---|---|---|---|---|---|
| 0.0032 | 0.0033 | 0.237 | 0.7195 | 0.8588 | 0.9481 |
Rows with small norms (155 rows in the bottom 0.1%, the 20 smallest): 106175:'1997'(0.0032), 154832:'<|begin_of_video|>'(0.0032), 106213:' 2007'(0.0032), 106699:'1996'(0.0032), 106975:'1994'(0.0032), 126736:' 1988'(0.0032), 120130:'1937'(0.0032), 154872:''(0.0032), 104669:' 2010'(0.0032), 121308:'4500'(0.0032), 125447:' 52'(0.0032), 104054:' 2012'(0.0032), 119202:'1100'(0.0032), 125051:' 58'(0.0032), 133221:' ۲'(0.0032), 108932:' 2003'(0.0033), 121657:'1959'(0.0033), 124429:' 95'(0.0033), 123929:'1954'(0.0033), 113375:' 36'(0.0033)
A small norm does not mean that the token is unimportant or untrained.
Similarity between experts
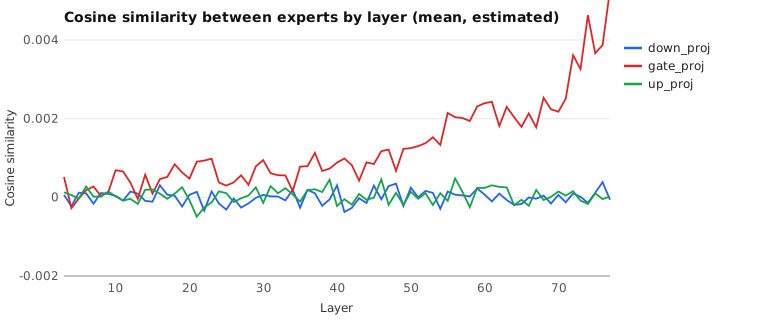
For matrices of the same kind in the same layer, the cosine similarity between experts was estimated with a 32×32 random projection (estimated). Mean over all layers: 4.3924e-04.
Measurement conditions
- mbscope 0.2.8 (result schema v1), Python 3.14.4, torch 2.13.0+cu130, safetensors 0.8.0, huggingface_hub 0.36.2, tokenizers 0.21.4, transformers 4.49.0
- Estimation criteria: outlier_sigma=6.0, embed_low_pct=0.1, power_iters=30, sketch_dim=32, top_channels=16, seed=20261002
- FP8 (F8_E4M3) weights were restored to fp32 by multiplying by the matching _scale_inv (block scales) before computation
- Input texts: ja: Natsume Sōseki, I Am a Cat, opening (Aozora Bunko 789_ruby_5639; source: Natsume Sōseki Zenshū 1, Chikuma Bunko), sha256 prefix
5d6b40f79b6a/ en: Jane Austen, Pride and Prejudice, opening of Chapter 1 (Project Gutenberg eBook #1342), sha256 prefix0a714a270435 - Computed on GPU NVIDIA GeForce RTX 3090 (CUDA 13.0, TF32 off) in fp32
- Measured with mbscope 0.2.7. The measurements were re-aggregated with mbscope 0.2.8 without re-measuring
Comments
…