Tongyi-MAI/Z-Image-Turbo — image generation record
Summary
- Size: 10.26B parameters in total; about 32.8GB of weight files.
- Structure: ZImagePipeline. Components: vae (AutoencoderKL), text_encoder (Qwen3Model), transformer (ZImageTransformer2DModel).
- Settings: 1024×1024 pixels, 9 steps, guidance 0.0. These values were read from the diffusers usage example in the model card (README); anything it does not specify uses the pipeline default.
- Speed: on one RTX 3090 in bf16, median 9.5 s per image (first image 10.2 s). Peak VRAM 21.7GB. The whole model was kept on the GPU.
- License: apache-2.0. Only models whose licenses allow publishing generated images are recorded.
One-line summary: ZImagePipeline · 10.26B params · 1024×1024 · 9 steps · 9.5 s/image (RTX 3090)
Images
Six fixed prompts, drawn with random seeds 1 and 2 (left: seed 1, right: seed 2). No retouching or cherry-picking.
1. Portrait
A photograph of an elderly fisherman mending a net on a wooden pier at dawn, soft natural light, 50mm lens
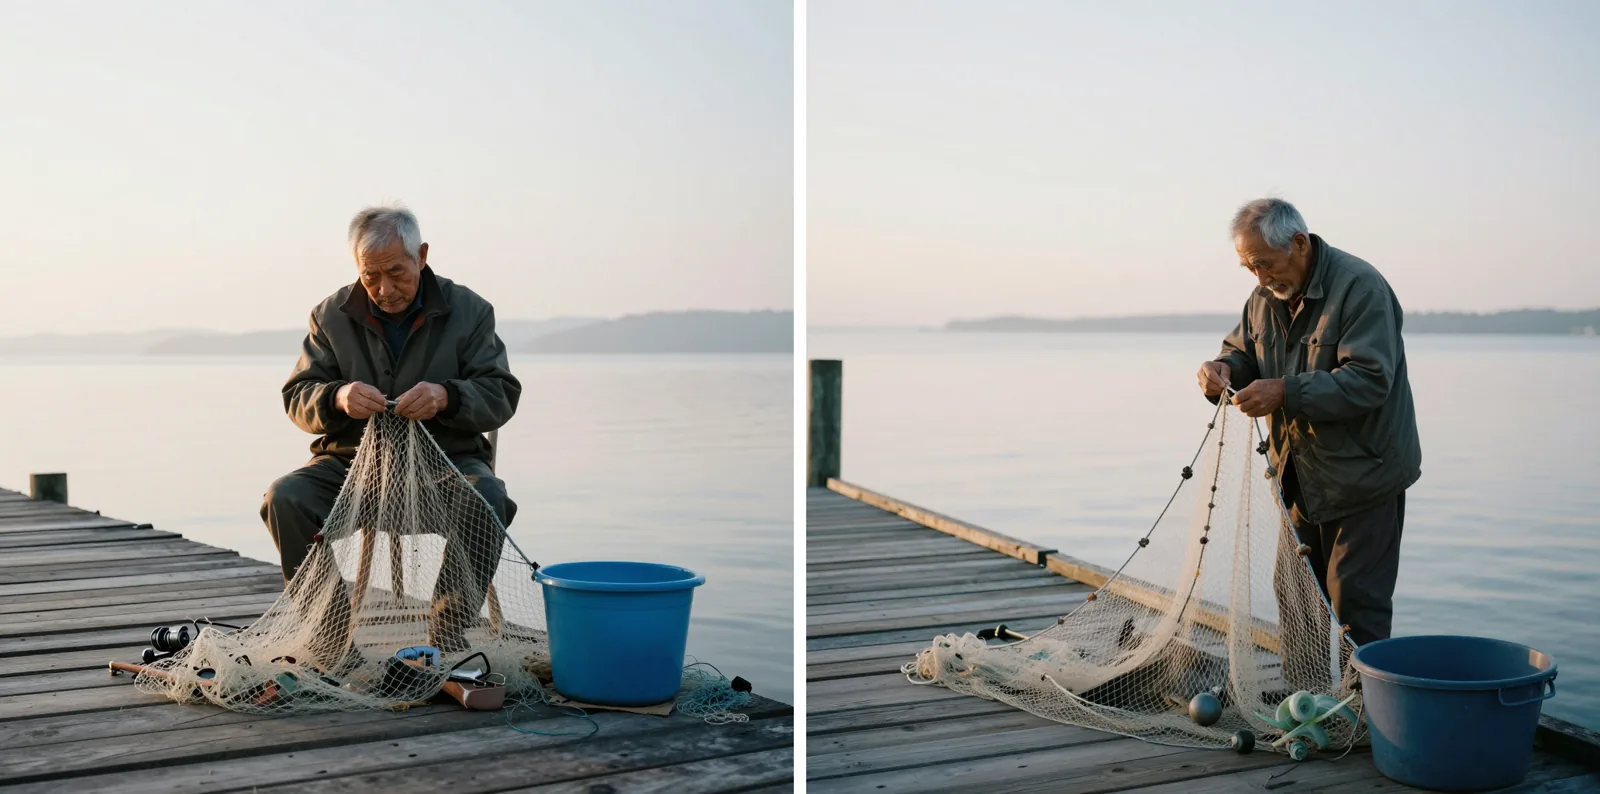
Time: 10.2 s / 9.4 s
2. Landscape
A moss-covered wooden bench in a quiet forest clearing, sunlight filtering through the trees
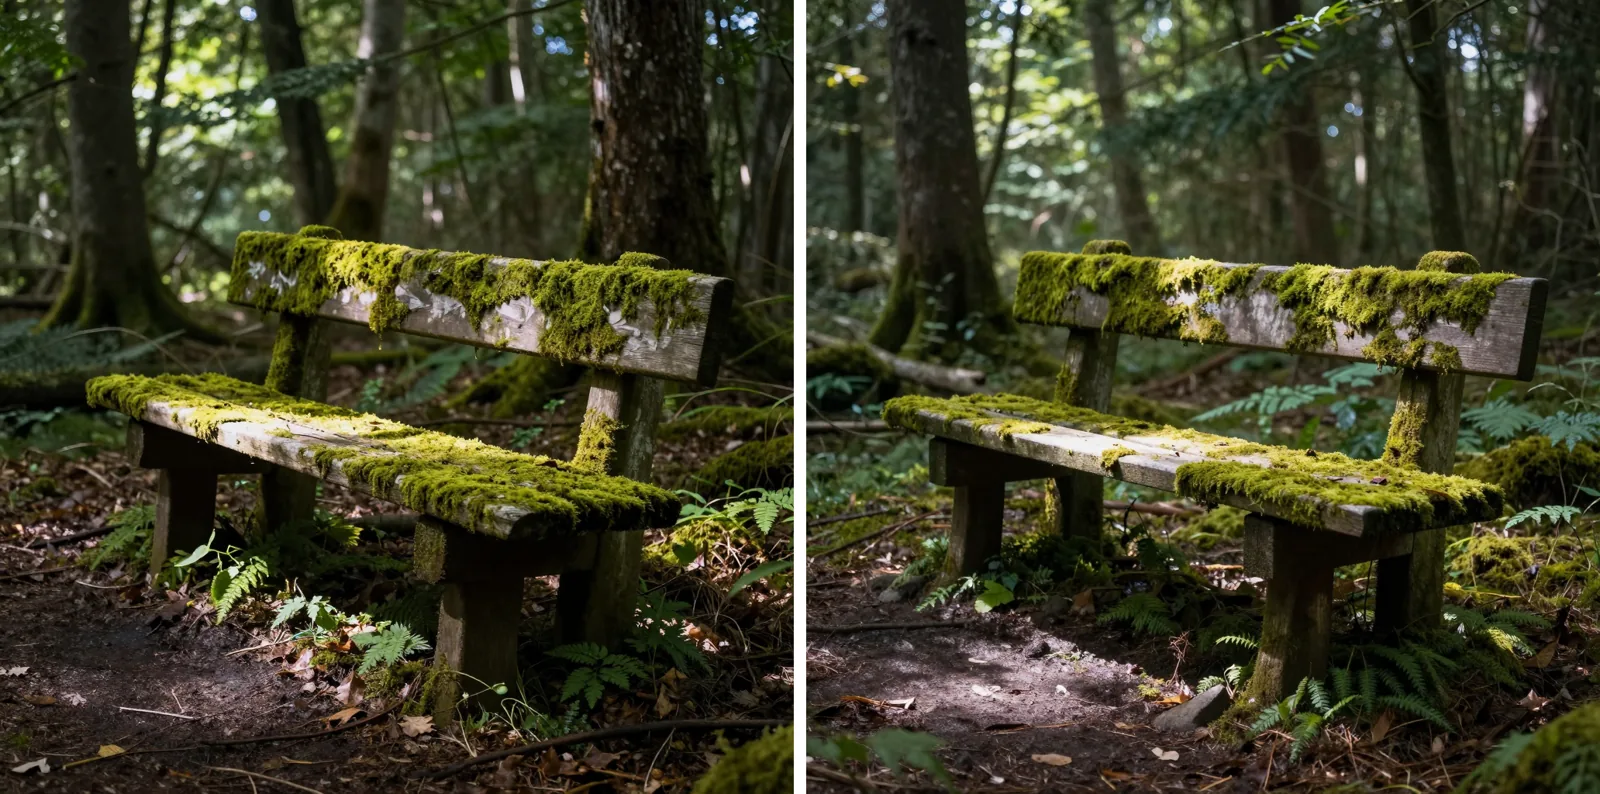
Time: 9.3 s / 9.4 s
3. Text
A small wooden shop sign that reads "MOSSBENCH" in painted letters, hanging above a door
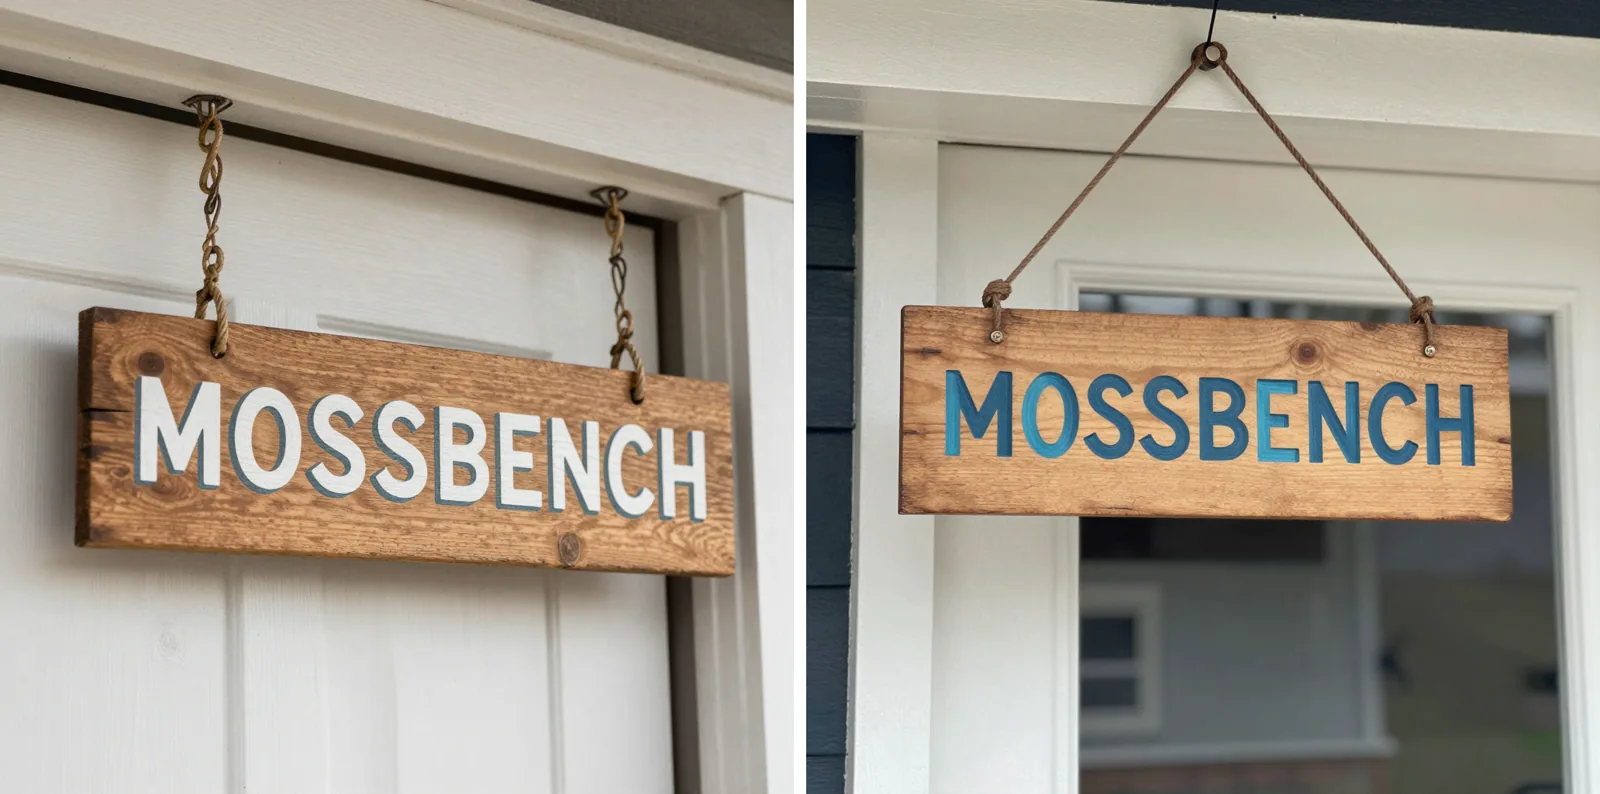
Time: 9.4 s / 9.4 s
4. Hands
Close-up of two hands holding a cup of green tea
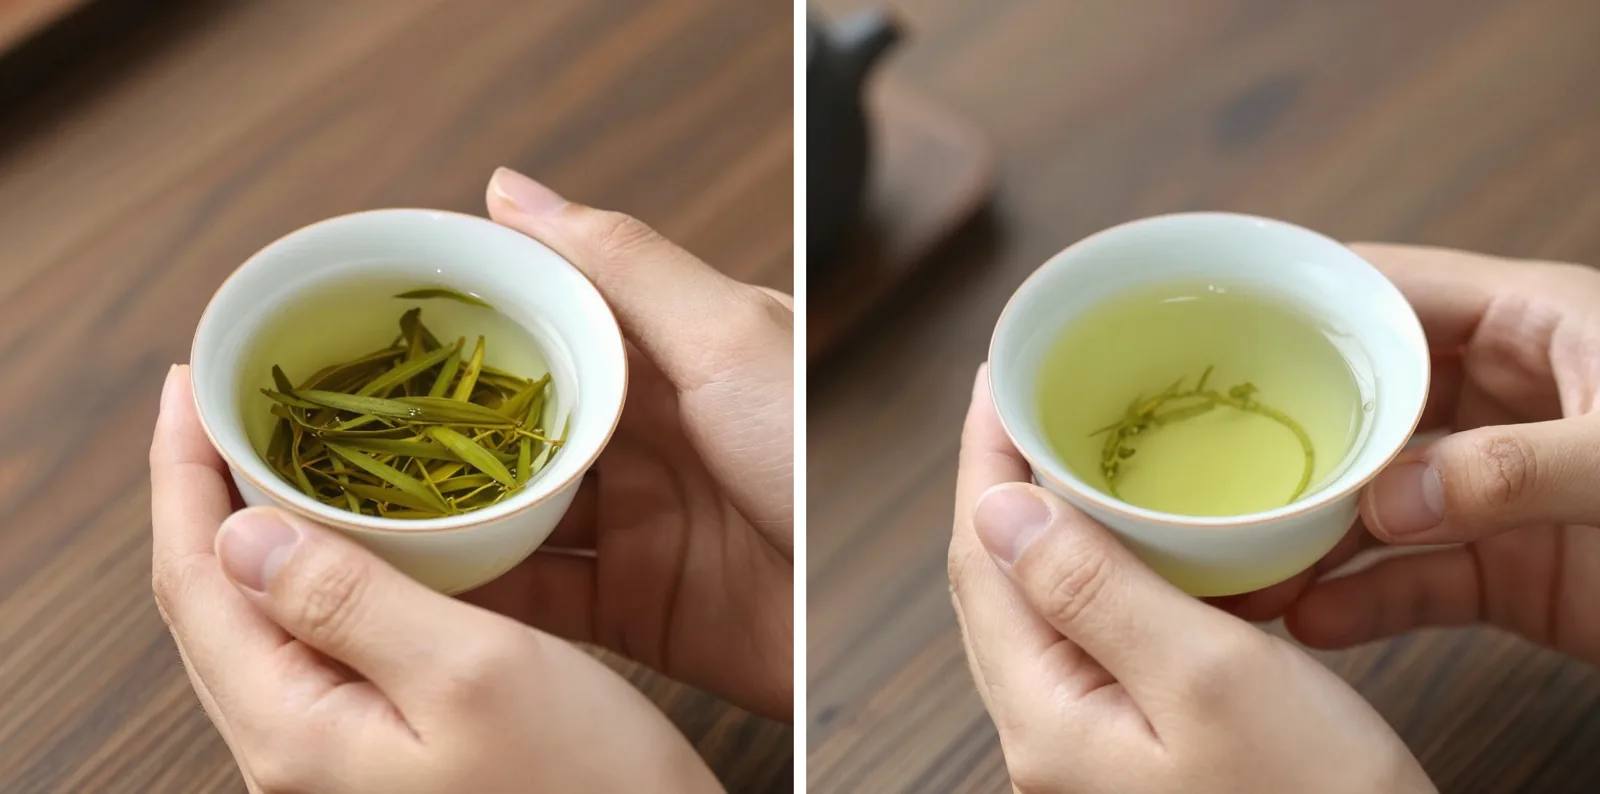
Time: 9.5 s / 9.5 s
5. Count
Three red apples and two blue cups on a white table, top view
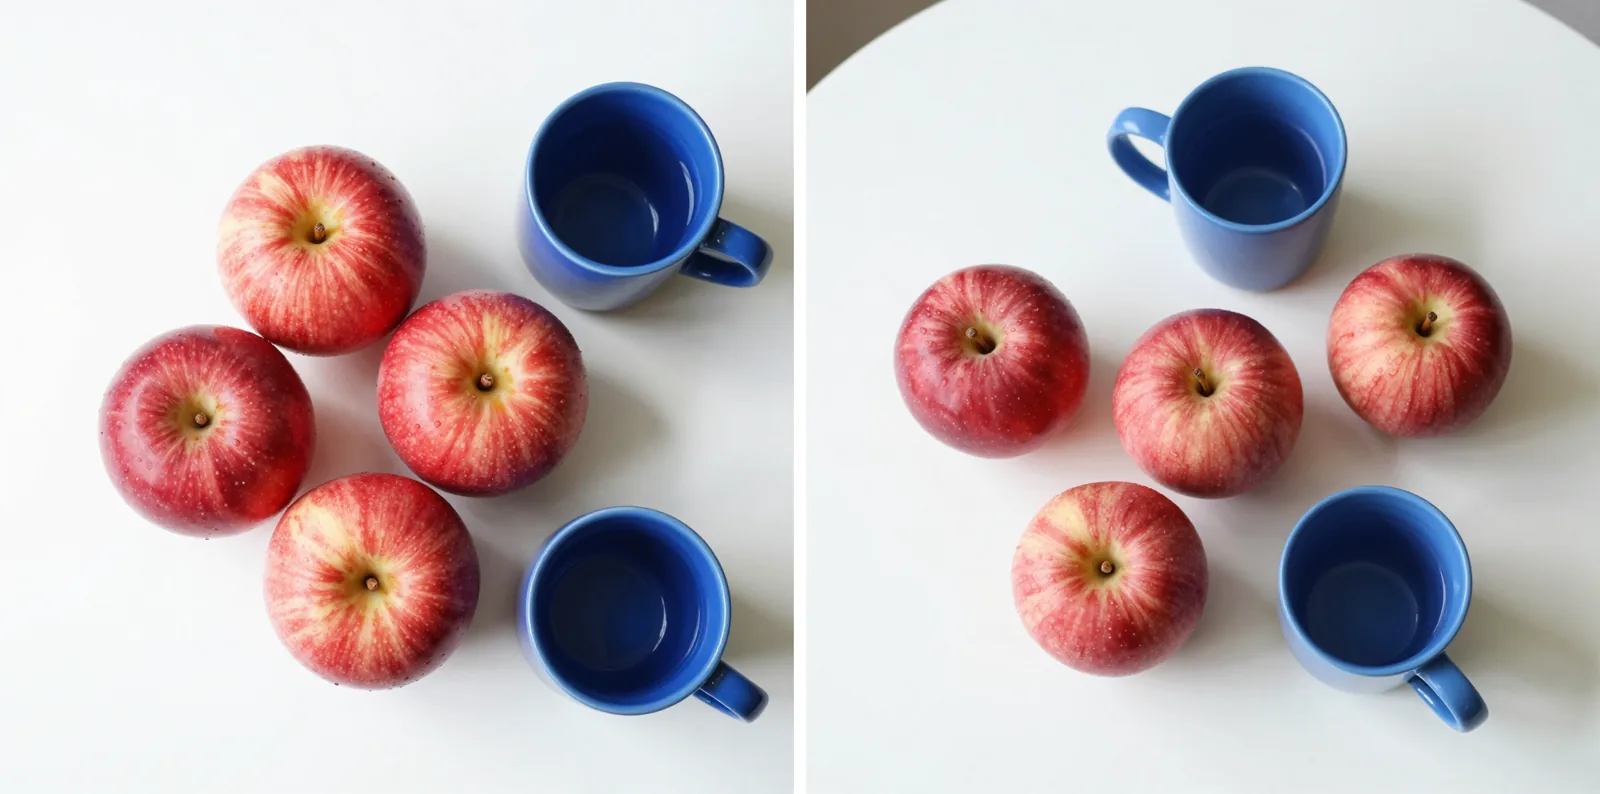
Time: 9.5 s / 9.5 s
6. Illust
A flat vector illustration of a cat reading a book under a desk lamp
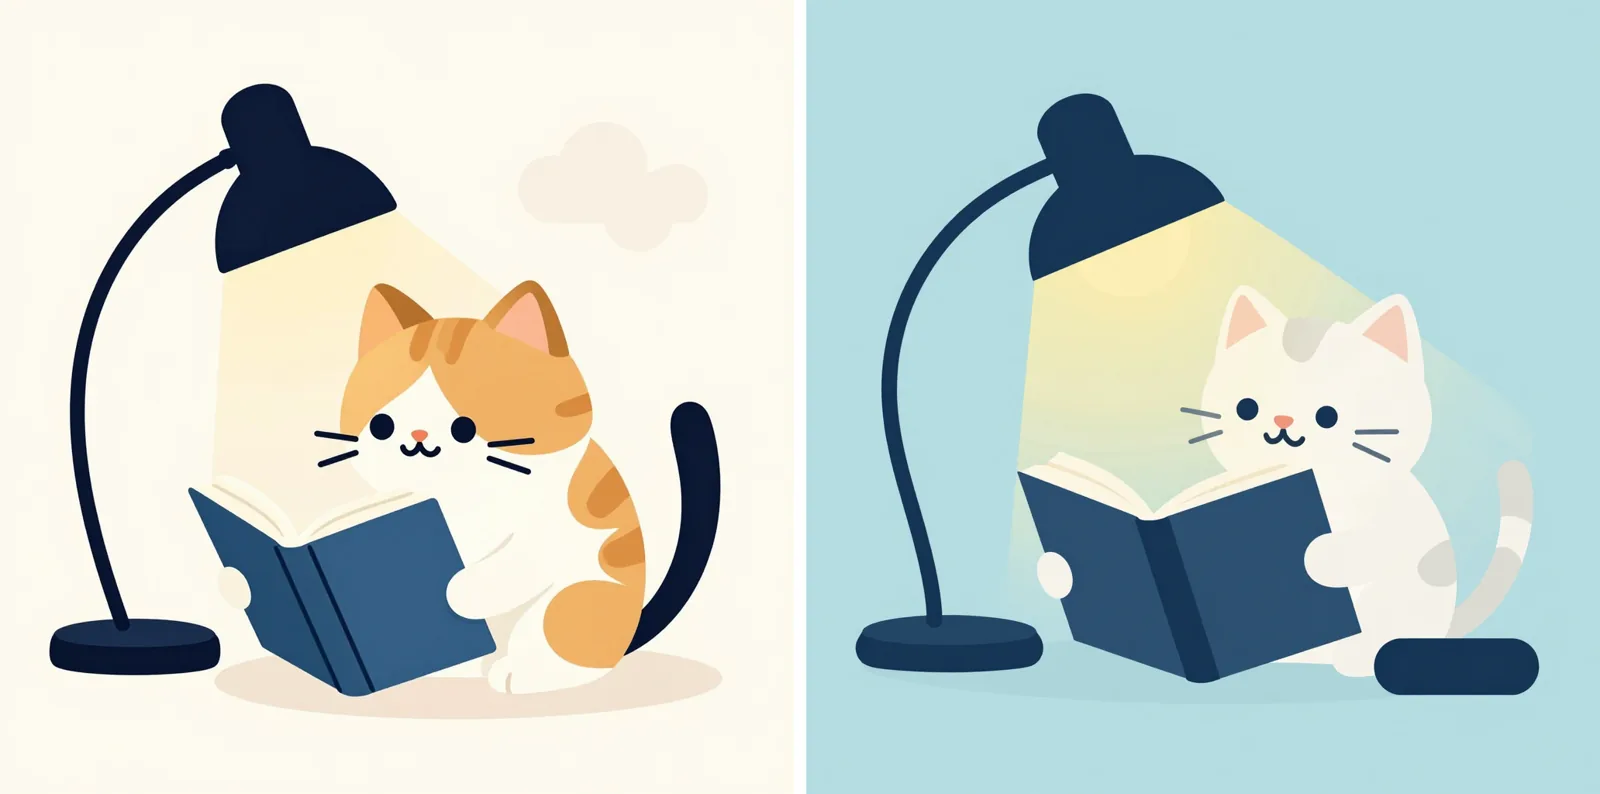
Time: 9.5 s / 9.5 s
Components
| Component | Class | Parameters | dtype |
|---|---|---|---|
| vae | AutoencoderKL | 83,819,683 | bfloat16 |
| text_encoder | Qwen3Model | 4,022,468,096 | bfloat16 |
| tokenizer | Qwen2Tokenizer | — | — |
| scheduler | FlowMatchEulerDiscreteScheduler | — | — |
| transformer | ZImageTransformer2DModel | 6,154,908,736 | bfloat16 |
Measurement conditions
- imgscope 0.1.1, Python 3.14.4, torch 2.13.0+cu130, diffusers 0.39.0, transformers 5.14.1, huggingface_hub 1.33.0, accelerate 1.15.0, safetensors 0.8.0
- GPU: NVIDIA GeForce RTX 3090, bf16, TF32 off. Random numbers from
torch.Generator('cpu').manual_seed(seed) - Placement: whole model on the GPU. Loading took 296 s
- Settings used: num_inference_steps=9 (README), guidance_scale=0.0 (README), height=1024 (README), width=1024 (README), max_sequence_length=512 (default)
- Pipeline defaults (for reference): {'num_inference_steps': 50, 'guidance_scale': 5.0, 'height': None, 'width': None, 'max_sequence_length': 512}
- Time is measured per image until the GPU finishes. VRAM is the peak memory allocated by torch
- Model: Tongyi-MAI/Z-Image-Turbo (revision
f332072aa78b)
Comments
…