deepseek-ai/DeepSeek-V3 — model analysis
Summary
- Size: The model consists of about 684 billion numbers (parameters). Its saved files total about 689GB.
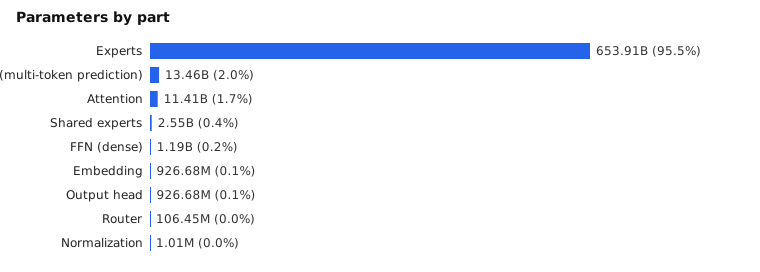
- Structure: A mixture-of-experts (MoE) model that, for each input, selects only 8 of its 256 experts. Of about 684 billion parameters in total, about 37.5 billion are used per computation step. About 96% of the parameters are assigned to the experts, about 2% to the multi-token prediction part (MTP), and about 2% to the part that reads context (attention).
- Japanese text: In Japanese, one token holds about 1.4 characters. In English, one token holds about 4.2 characters. For the same number of characters, Japanese needs about 3.0 times as many tokens as English. Of its 128,815 vocabulary entries, 36,086 contain kana or kanji.
- Context length: The limit written in the config (max_position_embeddings) is 163,840 tokens, roughly 230,000 Japanese characters or 690,000 English characters.
- Skew in values: Values inside the model flow in groups of 7,168. Position 2010 was among the positions where outliers (extremely large values) appear most often, in all 61 layers. Position 2010 also appeared in the tally of positions where normalization-layer weights take extreme values (98 of 245 normalization layers). This kind of skew is generally considered a cause of accuracy loss when a model is compressed (quantized).
One line: MoE (8 of 256 experts active) · deepseek_v3 · 61 layers · 684.49B params · 37.51B active · MLA · context 163,840 · vocab 129,280
Basic information
- Model: deepseek-ai/DeepSeek-V3 (revision
e815299b0bcb, config.json) - License: not stated
- Declared base_model: none
- Storage dtypes: F8_E4M3 680.57B, BF16 3.92B, F32 41.56M
Architecture (stage 0)
Parameters by part
Counted from the tensor shapes in the safetensors headers (measured).
| Part | Parameters | Share |
|---|---|---|
| Experts | 653,908,770,816 | 95.53% |
| MTP (multi-token prediction) | 13,463,426,304 | 1.97% |
| Attention | 11,413,422,080 | 1.67% |
| Shared experts | 2,554,331,136 | 0.37% |
| FFN (dense) | 1,189,085,184 | 0.17% |
| Embedding | 926,679,040 | 0.14% |
| Output head | 926,679,040 | 0.14% |
| Router | 106,445,312 | 0.02% |
| Normalization | 1,006,592 | 0.00% |
Structure
Values from config.json.
| Item | Value |
|---|---|
| model_type / architectures | deepseek_v3 / DeepseekV3ForCausalLM |
| Layers | 61 |
| Hidden size | 7,168 |
| FFN intermediate size | 18,432 |
| Attention type | MLA |
| Heads / KV heads / head dim | 128 / 128 / 56 |
| MLA settings | q_lora_rank=1536, kv_lora_rank=512, qk_rope_head_dim=64, qk_nope_head_dim=128, v_head_dim=128 |
| Sliding window | — (use_sliding_window=—) |
| Layer types (layer_types) | — |
| RoPE θ | 10,000 |
| RoPE scaling | {'beta_fast': 32, 'beta_slow': 1, 'factor': 40, 'mscale': 1.0, 'mscale_all_dim': 1.0, 'original_max_position_embeddings': 4096, 'type': 'yarn'} |
| Partial rotary (partial_rotary_factor) | — |
| Context length (max_position_embeddings) | 163,840 |
| Tied input/output embeddings | No |
| Activation | silu |
| Normalization ε | 1.000e-06 |
MoE configuration
Expert counts come from both config and tensor names (MTP layers excluded). Active parameters = total − MTP − expert part + expert part × active ÷ experts (computed).
| Item | Value |
|---|---|
| Experts (config) | 256 |
| Experts counted from tensor names (count: layers) | 256:58 layers |
| Active experts per token | 8 |
| Shared experts | 1 |
| MoE layers | 58 |
| Leading dense layers (first_k_dense_replace) | 3 |
| Expert parameters | 653.95B |
| Active parameters | 37.51B |
| MTP parameters (excluded from active) | 13.46B |
config vs. actual tensors
Values in config.json side by side with the actual tensor shapes (measured).
| Item | config | Actual | Match | Source of actual |
|---|---|---|---|---|
| vocab_size | 129,280 | 129,280 | Yes | model.embed_tokens.weight |
| hidden_size | 7,168 | 7,168 | Yes | model.embed_tokens.weight |
| num_hidden_layers | 61 | 61 | Yes | largest layer index + 1 (excluding MTP layers) |
| intermediate_size | 18,432 | 18,432 | Yes | model.layers.0.mlp.gate_proj.weight |
| tie_word_embeddings (no output-head tensor) | No | No | Yes | tensor list |
| num_experts | 256 | 256 | Yes | tensor names |
Tokenizer
Results of tokenizing the fixed Japanese and English texts (see conditions) without special tokens (measured). "Tokens splitting a character" is the share of tokens that decode to a broken character (U+FFFD) on their own.
| Text | Characters | Tokens | Chars/token | Bytes/token | Tokens splitting a character | Round-trips exactly |
|---|---|---|---|---|---|---|
| Japanese | 449 | 316 | 1.421 | 4.256 | 3.2% | Yes |
| English | 1,201 | 284 | 4.229 | 4.327 | 0.0% | Yes |
Of 128,815 vocabulary entries, 36,086 (28.01%) contain at least one kana or kanji character and 30,674 contain two or more (loaded with tokenizers).
Special tokens and chat format
804 special tokens. BOS: <|begin▁of▁sentence|>, EOS: <|end▁of▁sentence|>. Chat template: present (2145 characters, sha256 prefix 3b8267e54b67).
Thinking tags: No, tool calls: Yes, FIM: No, image tokens: No (found by searching special-token names and the template text).
List of special tokens
<|begin▁of▁sentence|>, <|end▁of▁sentence|>, <|▁pad▁|>, <|place▁holder▁no▁0|>, <|place▁holder▁no▁1|>, <|place▁holder▁no▁2|>, <|place▁holder▁no▁3|>, <|place▁holder▁no▁4|>, <|place▁holder▁no▁5|>, <|place▁holder▁no▁6|>, <|place▁holder▁no▁7|>, <|place▁holder▁no▁8|>, <|place▁holder▁no▁9|>, <|place▁holder▁no▁10|>, <|place▁holder▁no▁11|>, <|place▁holder▁no▁12|>, <|place▁holder▁no▁13|>, <|place▁holder▁no▁14|>, <|place▁holder▁no▁15|>, <|place▁holder▁no▁16|>, <|place▁holder▁no▁17|>, <|place▁holder▁no▁18|>, <|place▁holder▁no▁19|>, <|place▁holder▁no▁20|>, <|place▁holder▁no▁21|>, <|place▁holder▁no▁22|>, <|place▁holder▁no▁23|>, <|place▁holder▁no▁24|>, <|place▁holder▁no▁25|>, <|place▁holder▁no▁26|>, <|place▁holder▁no▁27|>, <|place▁holder▁no▁28|>, <|place▁holder▁no▁29|>, <|place▁holder▁no▁30|>, <|place▁holder▁no▁31|>, <|place▁holder▁no▁32|>, <|place▁holder▁no▁33|>, <|place▁holder▁no▁34|>, <|place▁holder▁no▁35|>, <|place▁holder▁no▁36|>, <|place▁holder▁no▁37|>, <|place▁holder▁no▁38|>, <|place▁holder▁no▁39|>, <|place▁holder▁no▁40|>, <|place▁holder▁no▁41|>, <|place▁holder▁no▁42|>, <|place▁holder▁no▁43|>, <|place▁holder▁no▁44|>, <|place▁holder▁no▁45|>, <|place▁holder▁no▁46|>, <|place▁holder▁no▁47|>, <|place▁holder▁no▁48|>, <|place▁holder▁no▁49|>, <|place▁holder▁no▁50|>, <|place▁holder▁no▁51|>, <|place▁holder▁no▁52|>, <|place▁holder▁no▁53|>, <|place▁holder▁no▁54|>, <|place▁holder▁no▁55|>, <|place▁holder▁no▁56|> …
Weights (stage 1)
Analyzed 46,183 of 91,991 tensors (compute time 10.8 min). Each tensor was converted to fp32 for computation. Tensors excluded from analysis: FP8 scale (not a weight) (45808). The 788 tensors of the MTP (multi-token prediction) part (layer 61) were analyzed but kept out of the per-layer trends, outlier channels, normalization-layer dimensions, embedding rows, expert similarity and extremes below, so that only the main layers are counted. Weights stored in FP8 (45,808) were restored to fp32 by multiplying by their 128×128 block scales before computation.
Trends across layers
RMS is the root mean square of the elements. max|w| ÷ RMS is how many times larger the largest element is than a typical one. Excess kurtosis measures tail heaviness and is 0 for a normal distribution (all measured).
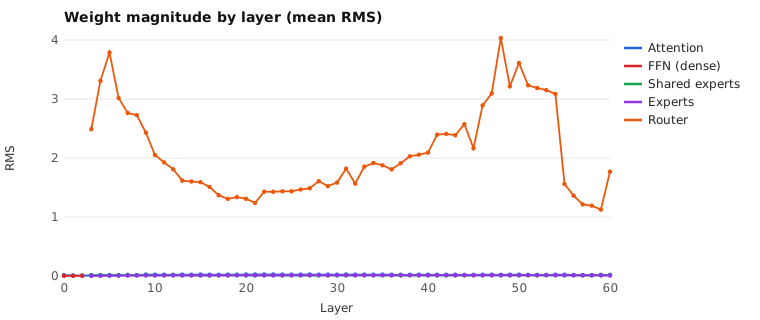
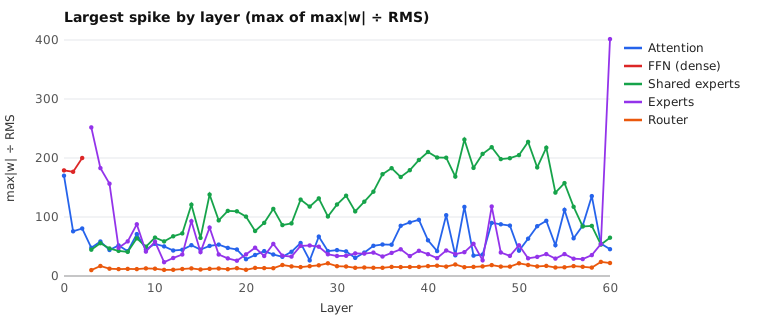
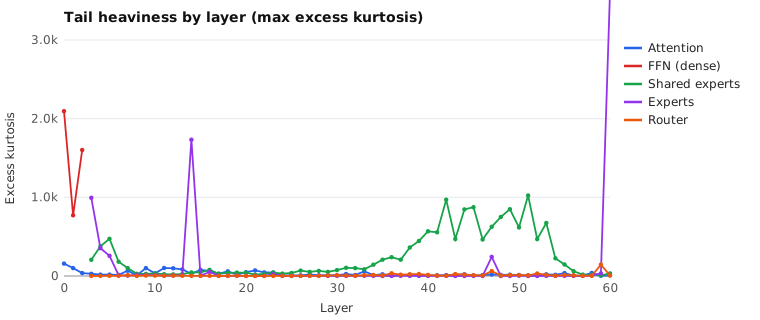
Matrices with the largest values: max|w| ÷ RMS 401.535 (model.layers.60.mlp.experts.53.down_proj.weight), excess kurtosis 3611.59 (model.layers.60.mlp.experts.53.down_proj.weight), outlier share 0.781% (model.layers.36.mlp.gate.e_score_correction_bias).
Outliers and outlier channels
An outlier is an element exceeding 6 times the standard deviation of its matrix. For each matrix that takes the hidden dimension as input, the columns with the most outliers (top 16) were collected, and the number of layers in which each column appeared was counted (measured).
| Hidden-dimension column | Layers it appeared in (of 61) |
|---|---|
| 2010 | 61 |
| 2372 | 61 |
| 2784 | 61 |
| 5426 | 61 |
| 2785 | 60 |
| 5070 | 60 |
| 317 | 59 |
| 2564 | 59 |
| 3500 | 59 |
| 5729 | 59 |
Normalization-layer weights
For each of the 245 normalization layers, the dimensions farthest from the median (top 16) were collected, and the number of normalization layers in which each dimension appeared was counted (measured).
| Dimension | Normalization layers it appeared in |
|---|---|
| 6441 | 106 |
| 6739 | 103 |
| 2010 | 98 |
| 3500 | 95 |
| 2785 | 94 |
| 1364 | 90 |
| 1969 | 87 |
| 5426 | 83 |
| 317 | 81 |
| 7000 | 80 |
Dimensions shared with the top 10 outlier channels above: 317, 2010, 2785, 3500, 5426.
Effective rank
Stable rank = (Frobenius norm)² ÷ (largest singular value)², divided by the matrix's shorter side to scale it to 0–1. The largest singular value is approximated by power iteration (30 steps) (estimated).
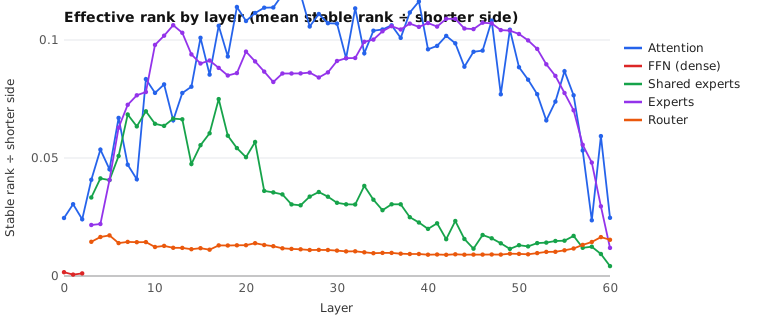
Stable rank ÷ shorter side by part:
| Part | Matrices | Min | Median | Max | Matrix with the minimum |
|---|---|---|---|---|---|
| Experts | 44544 | 7.6307e-04 | 0.0744 | 0.317 | model.layers.14.mlp.experts.202.down_proj.weight |
| MTP (multi-token prediction) | 780 | 0.0022 | 0.0255 | 0.3177 | model.layers.61.mlp.shared_experts.up_proj.weight |
| Attention | 305 | 0.0023 | 0.0431 | 0.4038 | model.layers.2.self_attn.o_proj.weight |
| Shared experts | 174 | 5.6018e-04 | 0.0188 | 0.1588 | model.layers.3.mlp.shared_experts.gate_proj.weight |
| Router | 58 | 0.009 | 0.0111 | 0.0172 | model.layers.42.mlp.gate.weight |
| FFN (dense) | 9 | 1.5599e-04 | 9.9366e-04 | 0.0029 | model.layers.0.mlp.gate_proj.weight |
| Embedding | 1 | 0.0166 | 0.0166 | 0.0166 | model.embed_tokens.weight |
| Output head | 1 | 0.0125 | 0.0125 | 0.0125 | lm_head.weight |
Embedding rows
Distribution of the length (norm) of each vocabulary entry's embedding row, and the rows with the smallest norms (bottom 0.1%) (measured).
model.embed_tokens.weight (129,280 rows)
| Min | Bottom 0.1% | Bottom 1% | Median | Top 1% | Max |
|---|---|---|---|---|---|
| 0.4932 | 0.5055 | 1.5467 | 3.196 | 3.9873 | 4.6582 |
Rows with small norms (130 rows in the bottom 0.1%, the 20 smallest): 128963:''(0.4932), 128957:''(0.4945), 129261:''(0.4974), 129269:''(0.4977), 128926:''(0.4978), 129118:''(0.498), 128940:''(0.498), 128933:''(0.4985), 129017:''(0.4992), 128954:''(0.4996), 129203:''(0.4998), 129125:''(0.5), 129062:''(0.5), 128888:''(0.5002), 128894:''(0.5004), 129012:''(0.5008), 129046:''(0.5008), 128986:''(0.5008), 128969:''(0.5009), 128989:''(0.5011)
lm_head.weight (129,280 rows)
| Min | Bottom 0.1% | Bottom 1% | Median | Top 1% | Max |
|---|---|---|---|---|---|
| 1.0945 | 1.1017 | 4.0422 | 6.7939 | 8.4443 | 10.521 |
Rows with small norms (130 rows in the bottom 0.1%, the 20 smallest): 129189:''(1.0945), 129067:''(1.0965), 129136:''(1.0967), 128842:''(1.0968), 129277:''(1.097), 128944:''(1.0972), 129044:''(1.0975), 129208:''(1.0975), 129269:''(1.098), 128927:''(1.0981), 128894:''(1.0983), 129188:''(1.0985), 129180:''(1.0986), 129077:''(1.0986), 128943:''(1.0987), 129008:''(1.0987), 129059:''(1.0989), 128908:''(1.0989), 129099:''(1.0989), 128911:''(1.099)
A small norm does not mean that the token is unimportant or untrained.
Similarity between experts
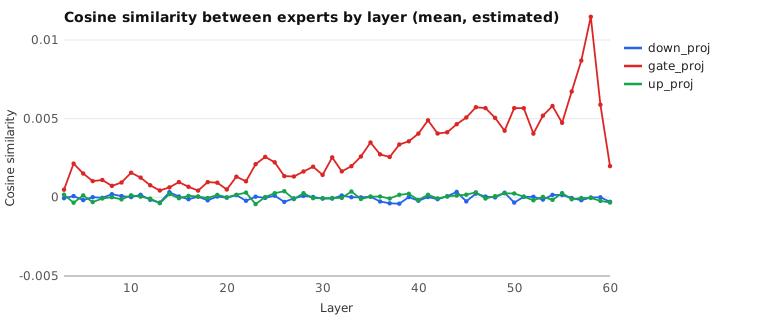
For matrices of the same kind in the same layer, the cosine similarity between experts was estimated with a 32×32 random projection (estimated). Mean over all layers: 9.8575e-04.
Measurement conditions
- mbscope 0.2.1 (result schema v1), Python 3.14.4, torch 2.13.0+cu130, safetensors 0.8.0, huggingface_hub 0.36.2, tokenizers 0.21.4, transformers 4.49.0
- Estimation criteria: outlier_sigma=6.0, embed_low_pct=0.1, power_iters=30, sketch_dim=32, top_channels=16, seed=20261002
- FP8 (F8_E4M3) weights were restored to fp32 by multiplying by the matching _scale_inv (block scales) before computation
- Input texts: ja: Natsume Sōseki, I Am a Cat, opening (Aozora Bunko 789_ruby_5639; source: Natsume Sōseki Zenshū 1, Chikuma Bunko), sha256 prefix
5d6b40f79b6a/ en: Jane Austen, Pride and Prejudice, opening of Chapter 1 (Project Gutenberg eBook #1342), sha256 prefix0a714a270435 - Run: 2026-10-02T17:17:22+09:00 – 2026-10-02T21:27:40+09:00, computed on GPU NVIDIA GeForce RTX 3090 (CUDA 13.0, TF32 off) in fp32
- Measured with mbscope 0.1.9. The measurements were re-aggregated with mbscope 0.2.1 on 2026-10-03T08:31:44+09:00 without re-measuring
- The text of this record was generated with mbscope 0.2.2 (measured with 0.2.1)
Comments
…